


On this page
IMAGE_URL_HERE in this block's data-image-url attribute with your final image link.
IMAGE_URL_HERE
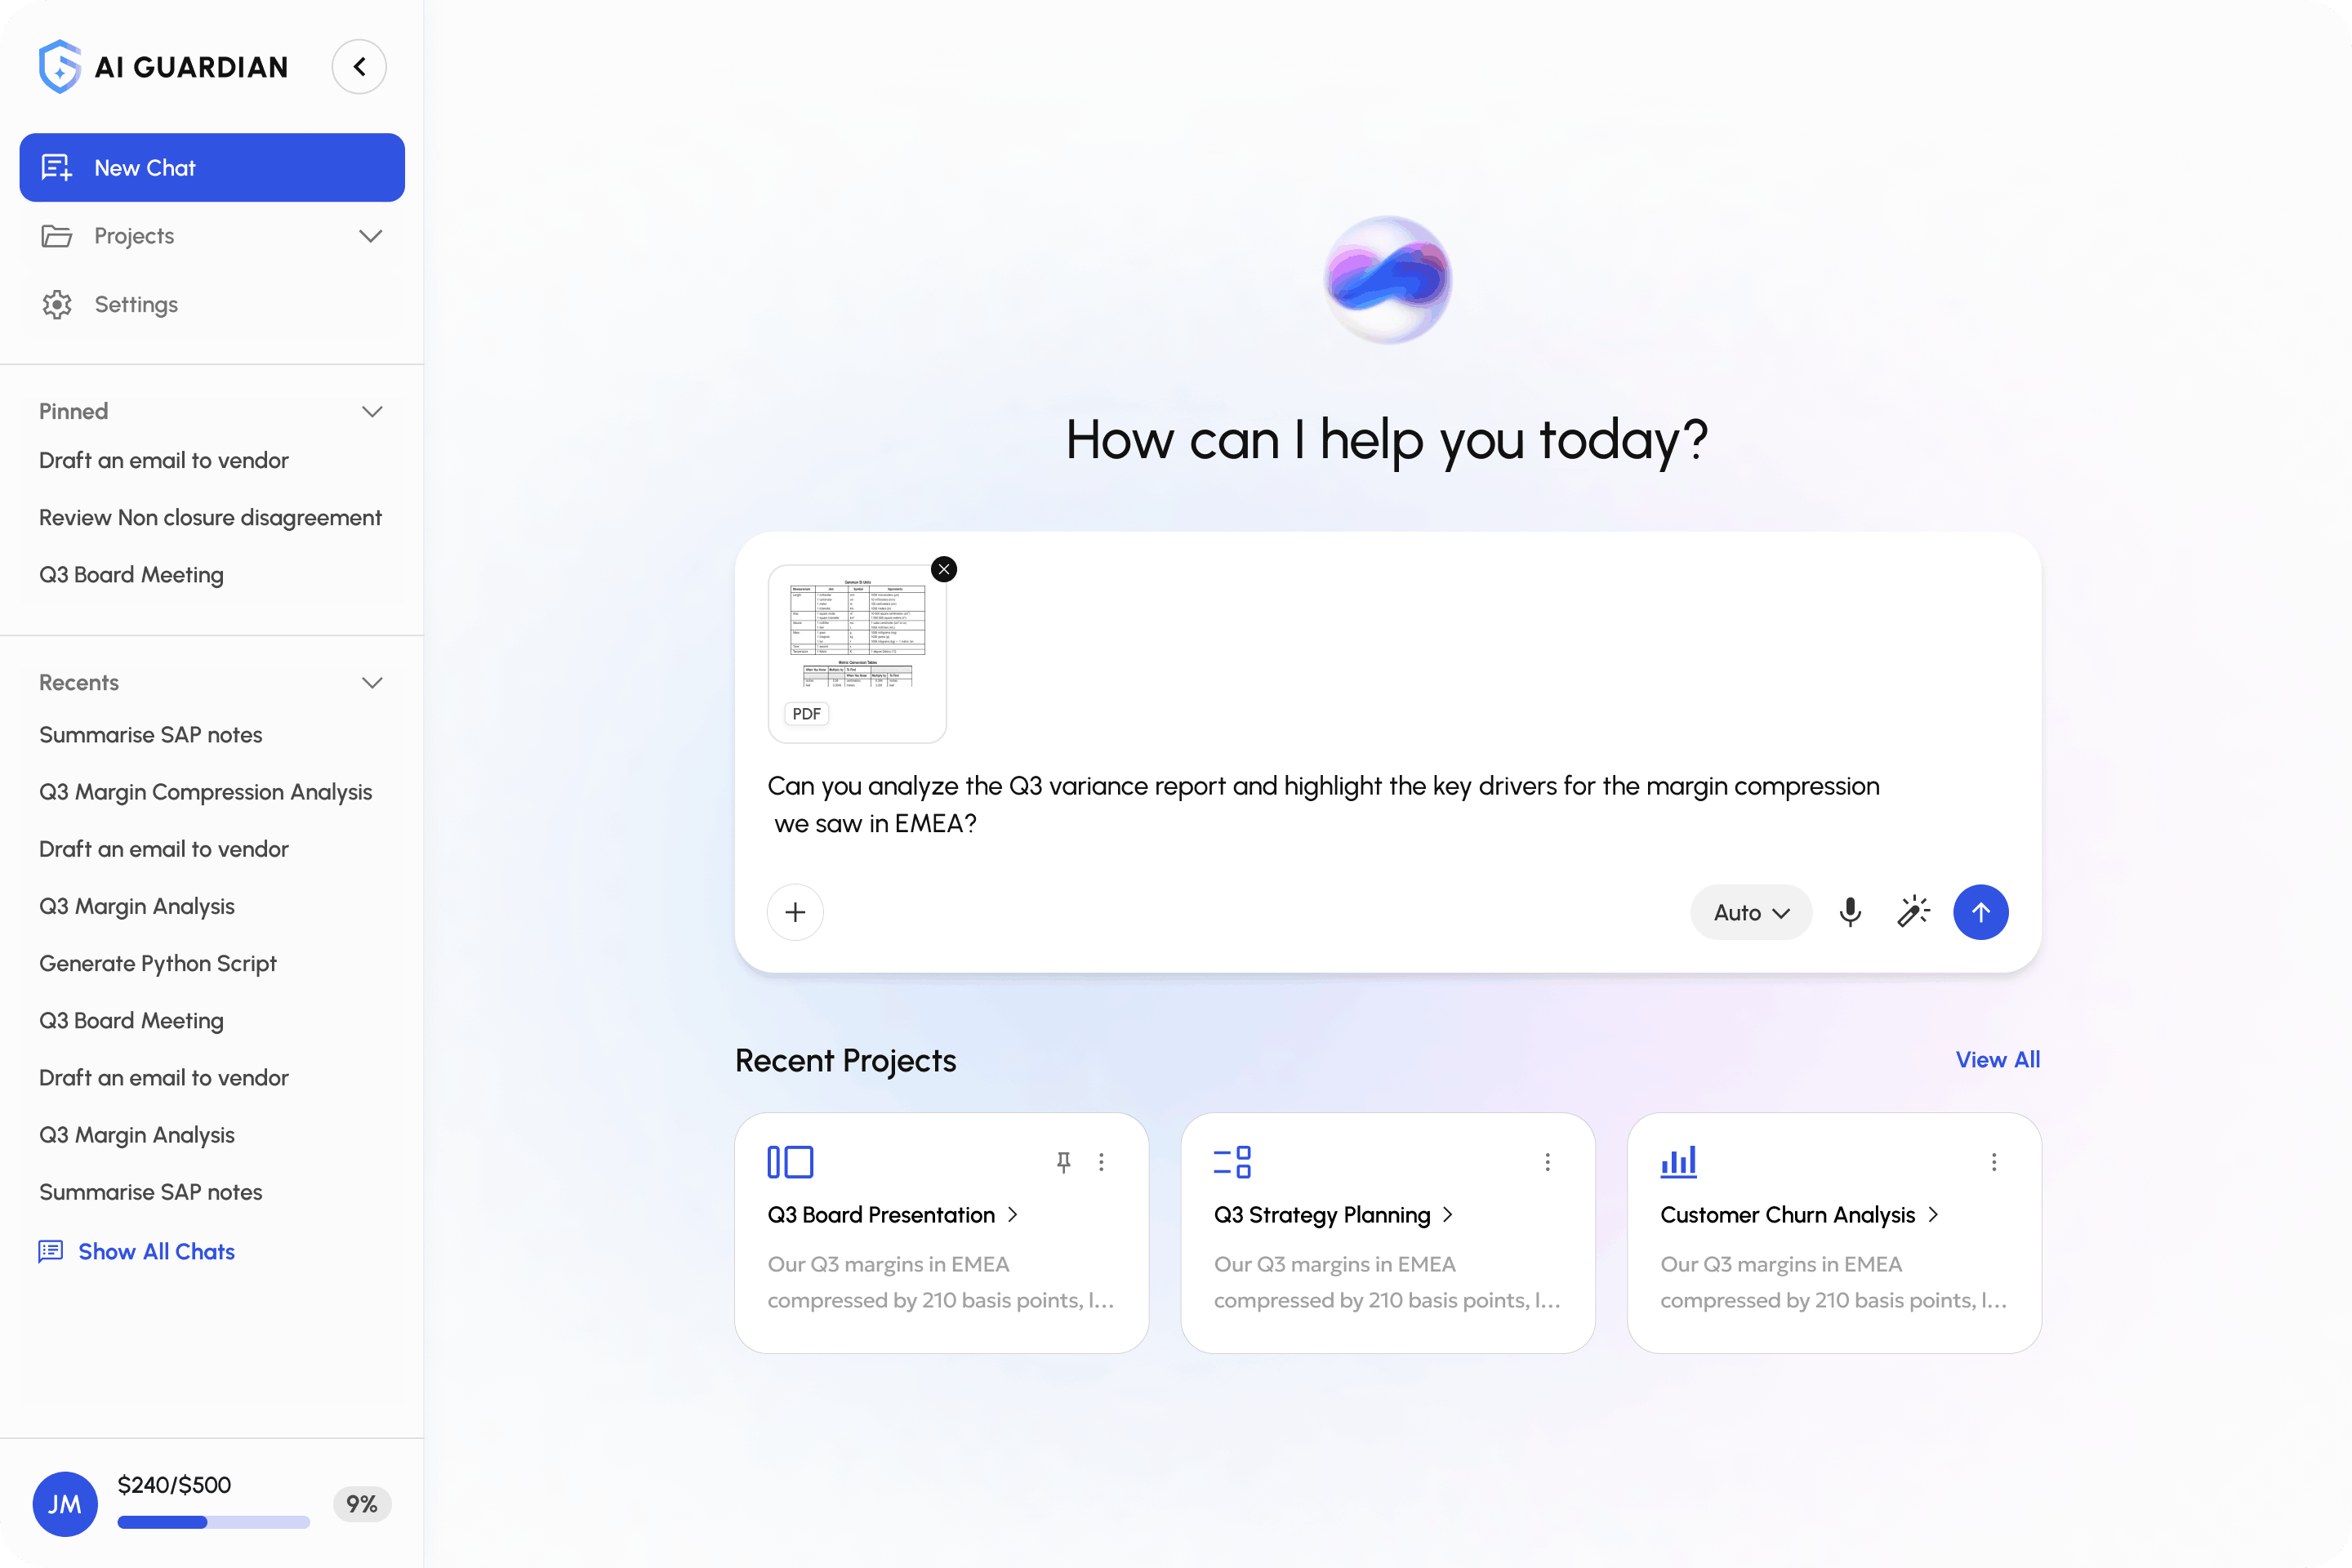
An enterprise LLM gateway gives organizations one control point between employees, applications, agents, and AI model providers. Instead of implementing identity, model access, sensitive-data handling, cost controls, and logging separately inside every AI tool, those rules can be applied centrally.
That becomes more important as AI usage expands beyond one team or one provider. Microsoft and LinkedIn's 2024 Work Trend Index found that 78% of people already using AI at work were bringing their own AI tools, creating visibility and data-governance gaps for IT.
This guide explains how an enterprise LLM gateway works, what capabilities matter, where it differs from API and agent gateways, and how to evaluate build, open-source, SaaS, and private-tenant options.
Why direct LLM access breaks at scale
IMAGE_URL_HERE in this block's data-image-url attribute with your final image link.
IMAGE_URL_HERE
Direct provider access suits a pilot. As usage spreads across teams, providers, and applications, six problems tend to appear together, all from one gap: no shared layer between people and models.
- Shadow AI on personal accounts: prompts sit in free-tier accounts the company cannot audit or revoke.
- Sensitive data reaching providers: customer IDs, bank details, and contract text leave inside unmasked prompts and files.
- Frontier models for routine tasks: a lookup runs on the priciest model because nobody set a default.
- No identity-attributed audit trail: shared API keys show that a call happened, not who made it.
- Fragmented subscriptions across teams: each department buys its own seats, hiding total spend.
- Provider outages and lock-in: an app wired to one API fails with it, and switching means rewriting integrations.
See where your current AI access leaks data and spend
Map today's AI access paths against identity, redaction, routing, and cost controls with a Folio3 specialist.
What is an enterprise LLM gateway?
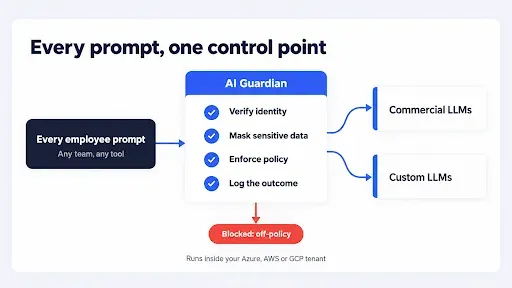
Definition: An enterprise LLM gateway is middleware that authenticates users, inspects and masks prompts, applies policy and budgets, routes each request to an approved model, and records the result. It replaces per-tool controls with one path, so security, finance, and IT share the same rules and logs.
Gateway vs proxy: the terms overlap. A proxy forwards traffic with little change; a gateway adds routing logic, policy enforcement, and observability.
A direct API is enough when:
- One team uses one model from one provider.
- Prompts carry no sensitive data.
- Nobody needs cost or usage attributed to people or departments.
The case for a gateway becomes stronger as additional teams, providers, sensitive workloads, cost controls, or compliance requirements appear.
How an enterprise LLM gateway works: request lifecycle
IMAGE_URL_HERE in this block's data-image-url attribute with your final image link.
IMAGE_URL_HERE
Every request follows six steps in a fixed order: identity first, inspection second, and no data reaches a provider before both finish.
- Authenticate the user via SSO: the request is tied to a named identity, role, and department.
- Inspect prompts and files: text and attachments are scanned for PII, secrets, and injection attempts, then masked or blocked.
- Apply policy and quotas: role rules, allowed topics, and department budgets are checked before the model call.
- Route to the approved model: the request goes to the model assigned to that role, with a fallback if it is unavailable.
- Orchestrate governed agents: agents and tools inherit the caller's identity and limits.
- Log cost and evidence: identity, model, tokens, cost, and every policy decision are recorded.
Failover boundary: failover is clean when a provider fails before a response starts. A mid-stream failure leaves partial output for the application to handle, so ask each vendor how it behaves.
LLM gateway vs API gateway vs agent and MCP gateway
The four layers differ in what they understand about the traffic and what they can control.
| Dimension | API gateway | LLM gateway | Agent gateway | MCP gateway |
|---|---|---|---|---|
| Traffic awareness | HTTP requests | Prompts, tokens, models | Multi-step workflows | Tool connections |
| Cost unit tracked | Requests | Tokens | Cost per task | Tool calls |
| Policy scope | Auth, rate limits | PII, budgets, model access | Agent permissions | Reachable tools |
| Primary user | Platform teams | Security, IT, AI platform | AI engineers | Security, platform |
| Example tools | Kong, NGINX | LiteLLM, OpenRouter | TrueFoundry Agent Gateway | Portkey (now Prisma AIRS AI Gateway) |
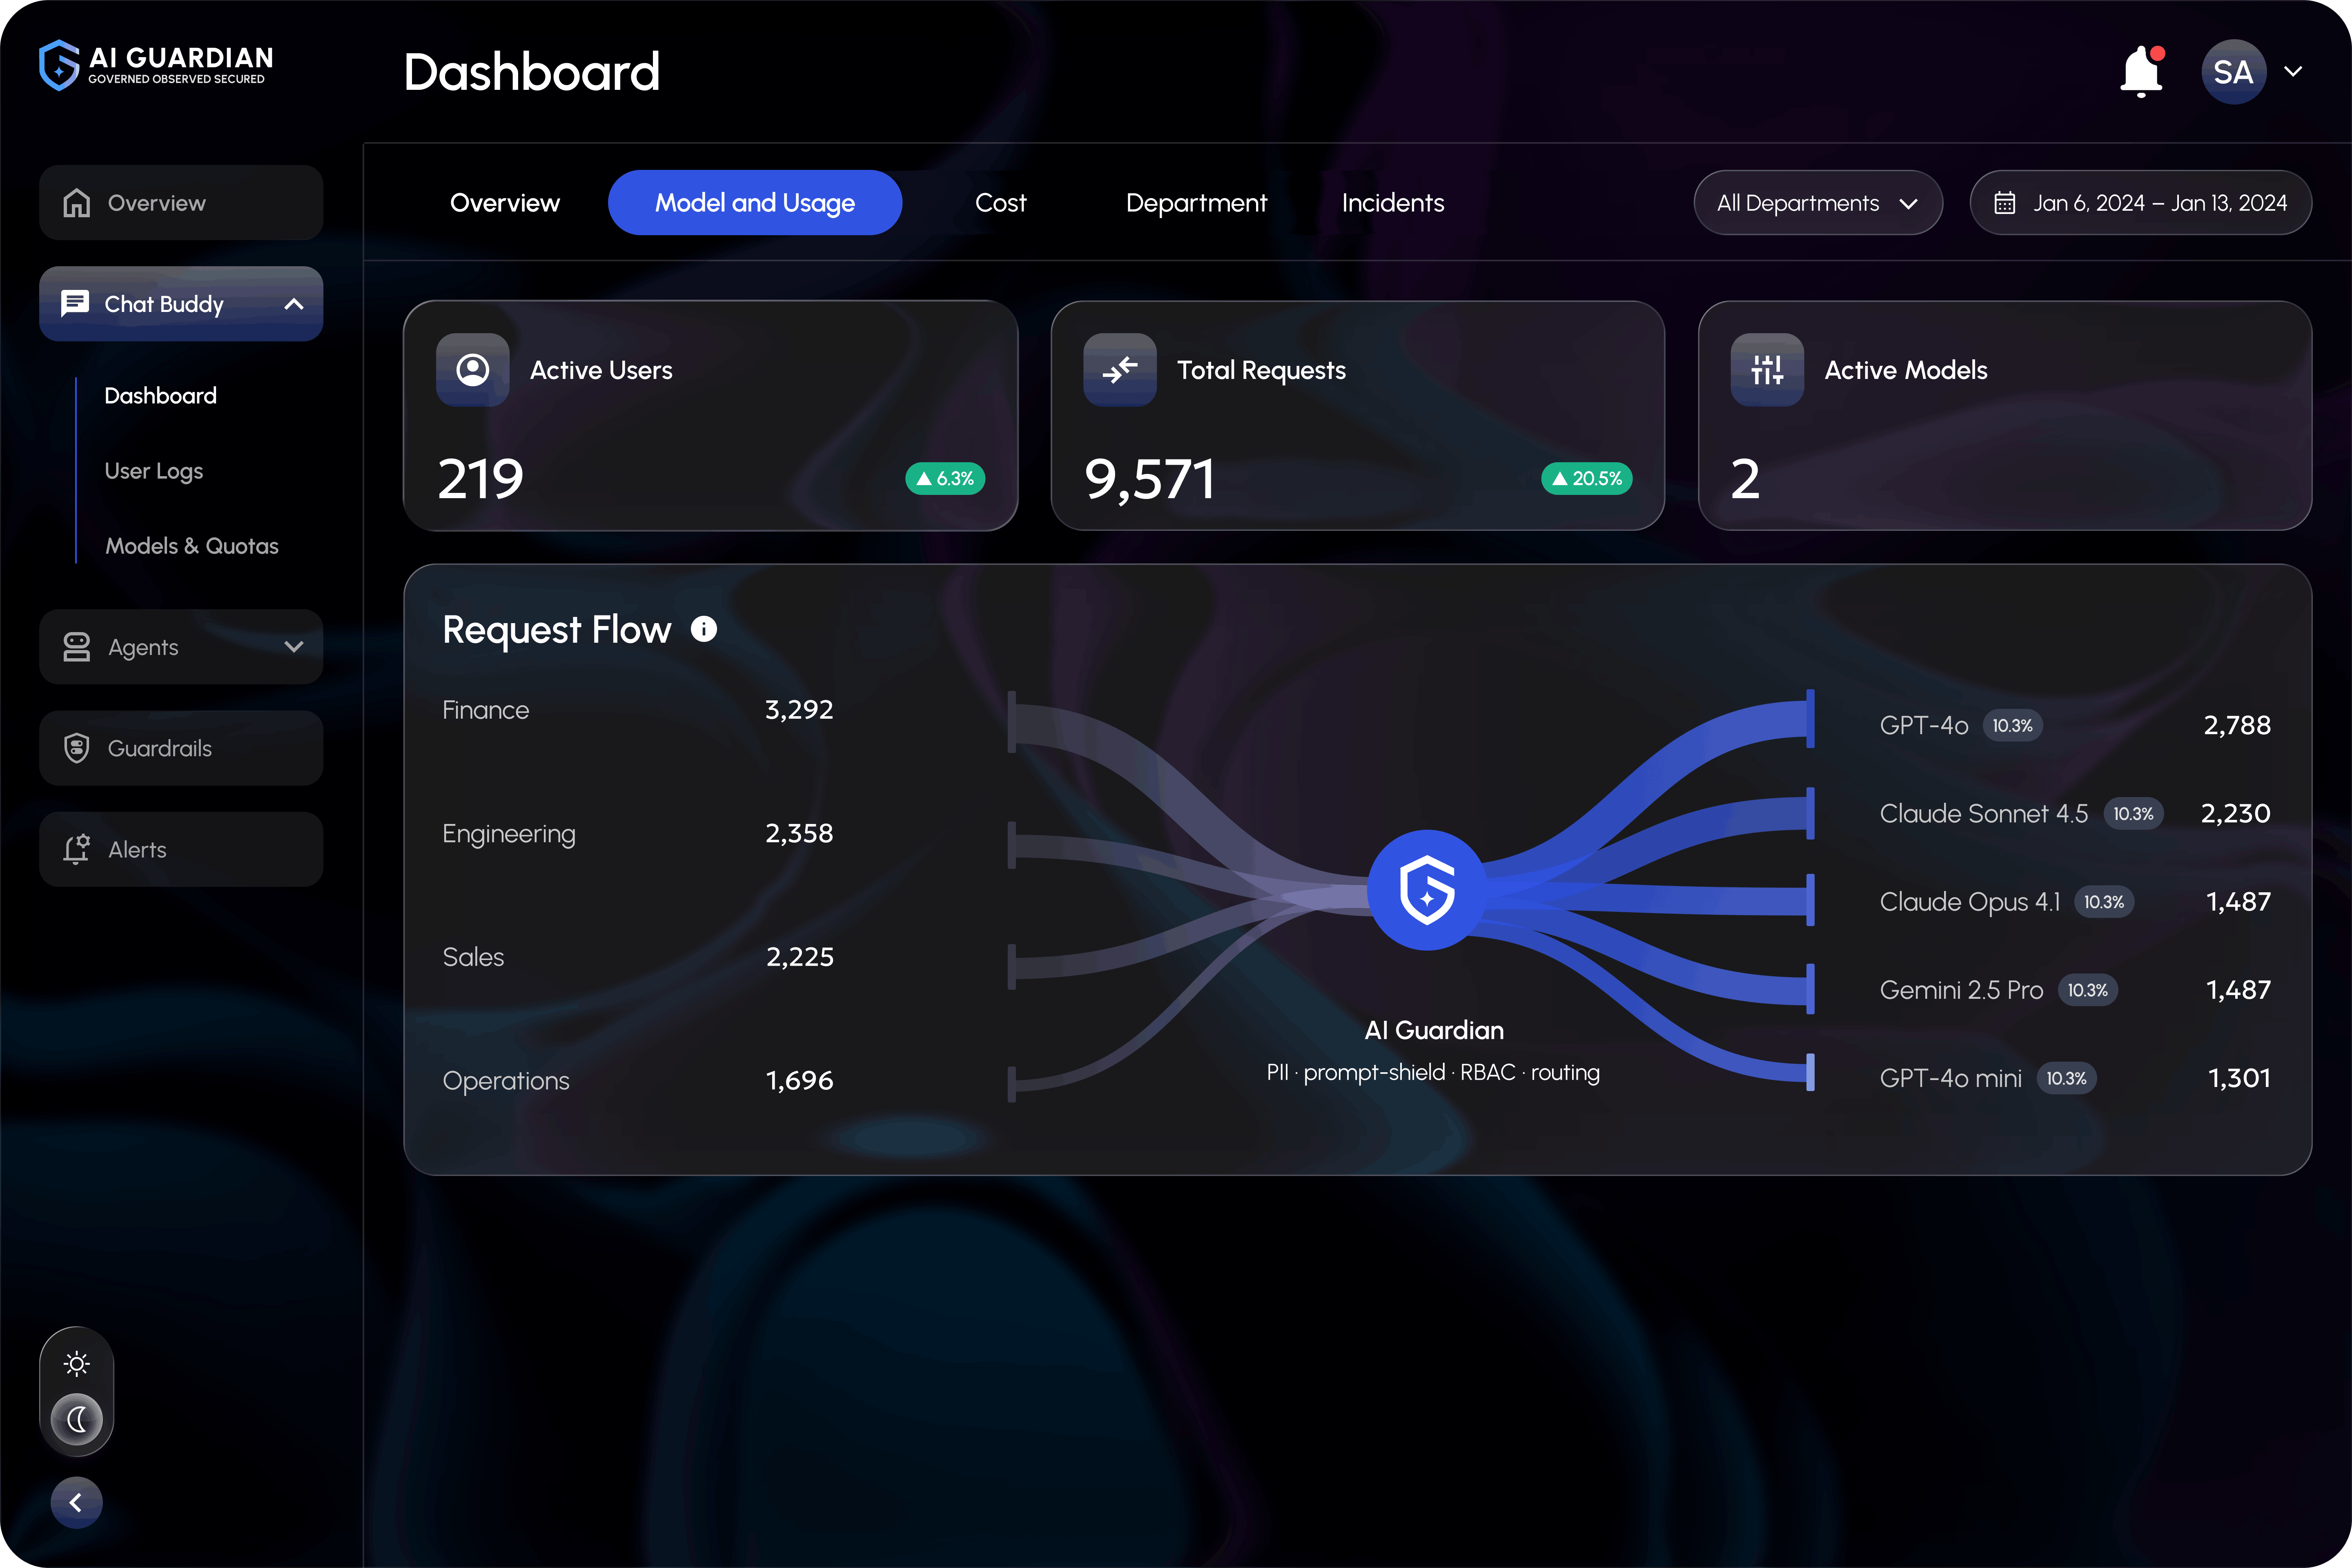
AI Guardian spans the LLM gateway layer and the agent governance layer, so agents run under the same identity, policy, and audit rules as employee prompts.
What core capabilities should enterprise LLM gateway software have?
Ten capabilities separate a governed gateway from a simple router. Test each against the last column with any vendor.
| Capability | Priority | Why it matters | What to verify |
|---|---|---|---|
| Unified multi-model access | Must have | One API replaces per-provider integrations | Commercial and custom models on one interface |
| SSO, RBAC and identity | Must have | Attributes every call to a person | Directory sync, offboarding behavior |
| PII and secret redaction | Must have | Limits regulated data reaching providers | Detection accuracy on your own files, multi-page documents, regional IDs |
| Prompt injection defense | Must have | Detects and applies controls to suspicious instructions in user, retrieved, and tool-supplied content | Test known and custom injection patterns across direct prompts, retrieved documents, and tool output |
| Off-domain policy enforcement | Depends | Keeps AI use to approved work | Per-role rules, block logging |
| Budgets, quotas and caps | Must have | Prevents unowned spend | Enforcement at request time |
| Model routing and fallback | Must have | Cuts cost, survives outages | Per-role routing, mid-stream handling |
| Audit logs and observability | Must have | Supports investigations | Identity on each record, retention control |
| Data residency and deployment | Depends | Keeps data in approved regions | Your tenant vs vendor cloud |
| Agent and tool governance | Growing | Agents multiply access paths | Identity inheritance, tool permissions |
Worked example: one prompt, start to finish
This illustration, built from AI Guardian's controls, shows what the six steps do to one request. Every identifier is fictional.
The prompt example: a finance analyst uploads a vendor invoice and asks, "Check that the IBAN and Iqama number match the vendor record, and summarize payment terms. Also plan my weekend trip."
| Step | What happens |
|---|---|
| Identity | SSO resolves the analyst, Finance department, and role |
| Inspection | The multi-page scan finds an IBAN and an Iqama number and replaces both with placeholders before the request leaves the tenant |
| Policy | "Plan my weekend trip" falls outside allowed topics, so it is blocked and logged; the invoice task continues |
| Routing | The analyst role maps to a mid-tier model approved for document review |
| Evidence | The record stores user, model, tokens, cost, and each policy decision |
The provider sees a masked invoice and a work question. The company keeps the identifiers, the decision trail, and the cost attribution.
AI Guardian: an enterprise LLM gateway solution built for governed adoption
What does AI Guardian add beyond a developer gateway? Routing, keys, and logging are table stakes. AI Guardian adds the layer that company-wide adoption needs: a place for employees to work, controls that line-of-business owners run themselves, and visibility for risk leaders.
- Employee workspace: staff use approved models in Teams, Slack, web, and mobile, so the governed path is also the convenient one.
- Multi-page and regional PII redaction: attached files are masked across every page, including IBAN, Iqama, and national ID formats, before any model call.
- Line-of-business governance: each LOB has its own hierarchy, owners, and model access, configured without engineering tickets.
- Department quotas and caps: LOB heads set and manage their own budgets, so spend has a named owner.
- Governed agent workflows: multi-agent chains run under the requester's identity, with the same redaction, policy, and audit controls as a prompt.
- Private tenant deployment: the platform runs in your Azure, AWS, or GCP tenant.
- Risk and executive dashboards: spend, blocked events, and audit history in one view for risk leaders and executives.
Capability scenario, not a client case study: a governed invoice review chain uses Invoice Analyzer, Policy Checker, and PO Retrieval agents under the requester's identity, so the audit trail shows who triggered it.
Types of LLM gateway software: which fits your team
Five categories exist, each built for a different buyer. Vendor details change, so confirm the current scope in each product's documentation.
| Category | Examples | Built for | Governance gaps to check |
|---|---|---|---|
| Open-source proxies | LiteLLM, Bifrost | Self-hosted control | You own hosting, upgrades, and hardening |
| Managed model routers | OpenRouter | Multi-provider access without infrastructure | Hosted only; no on-premises option per OpenRouter's own comparison |
| Developer AI gateways | Portkey (now Prisma AIRS AI Gateway), TrueFoundry, LLM Gateway | Teams shipping AI applications | Employee access and executive reporting are secondary |
| API management extensions | Kong AI Gateway | Companies already standardized on Kong | Fit depends on an existing Kong footprint |
| Governance control planes | AI Guardian | Security, IT and finance owners | Not built for maximum provider breadth or lowest raw latency |
Developer gateway vs AI Guardian control plane
| Factor | Typical developer gateway | AI Guardian |
|---|---|---|
| Primary design focus | Application traffic | Company-wide governed adoption |
| Employee workspace | Built or bought separately | Included |
| PII and document redaction | Prompt guardrails; file coverage varies | Multi-page, regional identifiers |
| Multi-agent teaming | Often separate | Governed, identity inherited |
| Off-domain enforcement | Varies | Enforced by role policy |
| Executive governance | Engineering dashboards | Risk and executive dashboards |
Not the right fit when: one engineering team needs raw multi-provider routing, the widest model catalog is the priority, or only backend application traffic exists.
Compare AI Guardian against your shortlist
Bring the gateways you are evaluating and see how each handles identity, redaction, routing, and audit on your own sample requests.
How to choose an enterprise LLM gateway solution
Teams often compare features before agreeing on who uses the tool and what must stay protected. Settle these seven questions first.
- Who uses it daily? Employees need a workspace; applications need APIs.
- Where must data stay? Vendor cloud or your own tenant.
- Which PII types matter? List identifiers in your documents, including regional ones.
- How is spend attributed? Cost should land on a person, team, and cost center.
- Does it govern agents? Check identity inheritance and tool permissions.
- What does security review need? Architecture diagram, data-flow map, SSO and RBAC model, log schema, retention.
- What is the three-year TCO? Include licenses, hosting, engineering time, and support.
By buyer: CISOs ask how redaction is verified. CIOs, CTOs, and CFOs ask about spend control and TCO. COOs and LOB heads want reports without IT tickets. Platform engineers ask about APIs, routing, and latency.
Should you build, self-host, or buy an LLM gateway?
Four routes exist, and engineering capacity plus governance depth decide between them. The comparison is qualitative because cost varies with scope.
| Factor | Build in-house | Self-host open source | Managed SaaS | Commercial platform in your tenant |
|---|---|---|---|---|
| Time to value | Longest | Fast start, slow governance | Fast | Days |
| Ops burden | Highest | High | Low | Low to moderate |
| Governance depth | What you build | Depends on edition | Depends on vendor | Built in |
| Data control | Full | Full | Data crosses to vendor | Full |
| Ongoing cost | Engineers | Infrastructure plus engineers | Usage or platform fees | License plus your cloud |
How does model rightsizing cut AI spend?
IMAGE_URL_HERE in this block's data-image-url attribute with your final image link.
IMAGE_URL_HERE
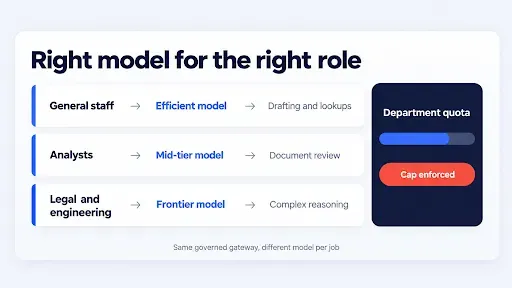
Most AI spend comes from routine work sent to expensive models. Rightsizing assigns models by role and task, and caps hold the savings as adoption grows.
- General staff: drafting and lookups on efficient models.
- Analysts: document analysis on mid-tier models.
- Legal and engineering: complex reasoning on frontier models under quotas.
- Department caps and off-domain blocking: stop one team consuming the budget and keep personal use off company spend.
Routine vs complex: Microsoft's model router guidance for agents says simple agent interactions typically make up 50 to 60% of traffic and can use cheaper models, with savings depending on workload mix. MintMCP reports a 40 to 70% cost reduction from moving 60 to 80% of requests to cheaper models, a vendor-reported range.
Modeled scenario: AI Guardian's model shows about 30% lower blended spend from role-based assignment and caps. It rests on stated assumptions and is not a benchmark or a guarantee.
Cheapest-model trap: Microsoft Research's Switchcraft study found, on tool-use tasks, that nominally cheaper models can cost more overall through token-heavy reasoning. Track cost per completed task, not per token.
Estimate your governed AI spend
Model role-based routing and department caps against your own usage in a governance consultation.
How long does implementation take?
Phase 1 is decisions, not engineering. Agreeing policy first keeps Phase 2 short.
Phase 1: Align
- Policies: record what is allowed, restricted, and prohibited.
- Hierarchy and roles: define LOBs, owners, and role mappings.
- Model access and quotas: agree on which roles reach which models and each department's budget.
Phase 2: Configure and deploy
- Configuration and SSO: load the hierarchy, connect your identity provider, and apply policies.
- Deployment and testing: install in your Azure, AWS, or GCP tenant and run test requests through every control.
AI Guardian currently targets a 4 to 5 business-day configuration and deployment window after rollout alignment, with timing varying by organizational complexity and integrations.
How enterprise LLM gateway software is priced
Four pricing models dominate, each moving cost somewhere different. Identify the vendor's model before comparing three-year totals.
- Platform fee on usage: a percentage of spend; OpenRouter lists 5.5% on credit purchases.
- Per-seat licensing: cost scales with headcount, not usage.
- Flat platform license: a fixed fee, often with scope tiers.
- Open source plus infrastructure: no license fee, but hosting, databases, and engineering time; LiteLLM, for example, requires a PostgreSQL instance.
AI Guardian investment: AI Guardian currently starts at $15K for implementation and $8K per quarter for the platform license, with final pricing based on scope, LOBs, integrations, and deployment requirements.
Get a scoped AI Guardian quote
Share your teams, integrations, and deployment requirements and get pricing scoped to your environment.
How does an LLM gateway handle security and compliance?
Each claim ties to an architectural control, so security review can check it.
- Deploys inside your tenant: Policy decisions and logs stay in your Azure, AWS, or GCP account.
- SSO, RBAC, and audit trails: Access follows directory roles and every request is recorded.
- Encryption and data residency: Gateway data, masking, and logs stay in your tenant's region. The masked prompt goes to the model provider's region, so match provider regions to your residency rules.
- Identity-attributed policy decisions: Each allow, mask, or block is stored against a named user.
- ISO 27001: Folio3 is ISO 27001 certified. The standard covers an organization's information security management, so prompt-level assurance comes from the controls above.
- Log retention (ask any vendor): Log metadata by default and keep full prompts only where policy requires, since prompts can contain PII.
| Stays in your tenant | Leaves your tenant |
|---|---|
| Identity checks and role mapping | The masked prompt, sent to the approved model provider |
| PII detection and masking | Nothing, if the approved model runs inside your tenant, such as a custom or privately hosted LLM |
| Policy decisions, quotas, audit logs | Nothing else: identity data, policy decisions, quotas, and logs stay in the tenant |
Why AI Guardian is different
- Designed for employee and agent adoption, not only backend APIs: staff and agents work through the same governed path.
- Identity and redaction before model ingress: every request is tied to a named user and masked before it leaves your tenant.
- Department-level model and spend controls: LOB heads own their model access, quotas, and caps.
- Runs in your cloud: deployed inside your Azure, AWS, or GCP tenant.
- Governed workspace included: an approved workspace in Teams, Slack, web, and mobile, not a separate purchase.
See the full platform on the AI Guardian product page.
Final words
An enterprise LLM gateway becomes necessary the moment AI use outgrows a single provider, a single team, or non-sensitive data. Developer gateways route traffic well, but security and finance need something different: identity on every request, redaction before data leaves, and reporting that ties spend to a named owner. If the answer to who uses it daily is your whole company, AI Guardian is built for that job: a governed workspace, masking in the request path, and a private deployment in your own Azure, AWS, or GCP tenant.
FAQs
What is an enterprise LLM gateway?
An enterprise LLM gateway is middleware between employees or applications and AI models. It authenticates each user, masks sensitive data, applies policy and budgets, routes the request to an approved model, and logs it to a named identity.
How is an LLM gateway different from an API gateway?
An API gateway manages HTTP traffic and has no model awareness. An LLM gateway understands tokens, cost, and model capabilities, so it can mask PII, enforce budgets, and route by model.
What features should enterprise LLM gateway software include?
Look for SSO and role-based access, PII and document redaction, prompt injection defense, department budgets, routing with fallback, and identity-attributed audit logs. Add private-tenant deployment and agent governance where they apply.
How much does an enterprise LLM gateway solution cost?
Pricing ranges from per-request usage fees to flat licenses, plus hosting and upkeep for open source. AI Guardian starts at $15K one-time setup and $8K per quarter for the license.
How is AI Guardian different from Portkey or LiteLLM?
Portkey (now Prisma AIRS AI Gateway) and LiteLLM center on developer and application traffic. AI Guardian adds an employee workspace, multi-page document redaction and executive governance, and deploys in your own Azure, AWS, or GCP tenant.
Written by the Folio3 AI Editorial Team. Reviewed by Abdul Sami, Head of AI Development at Folio3 AI, in September 2026.
Put every prompt behind one governed gateway
Your teams will use AI either way. The only choice is whether IT sees it. AI Guardian gives IT, Security, and Finance one place to approve models, mask sensitive data, cap spend, and trace every request to a named user, deployed in your own Azure, AWS, or GCP tenant in 4 to 5 business days.
In a 30-minute walkthrough, you will see:
- A live governed request: SSO identity, masking, and policy decisions on your own sample prompt
- Your exposure: where personal-account AI use, unmasked data, and unowned spend show up today
- Your numbers: setup from $15K and license from $8K per quarter, scoped to your teams
Listed on Microsoft Marketplace. ISO 27001 certified.

